RAG Evaluation: Metrics That Tell You Whether Your System Actually Works
By
Tom Dallimore
Published

You can build a RAG demo that answers five friendly questions correctly and still have absolutely no idea whether it works. That is the annoying bit. A green response in a playground feels reassuring, but it tells you very little about what happens when real users arrive with vague wording, typos, missing context, stale documents and questions nobody put in the demo script.
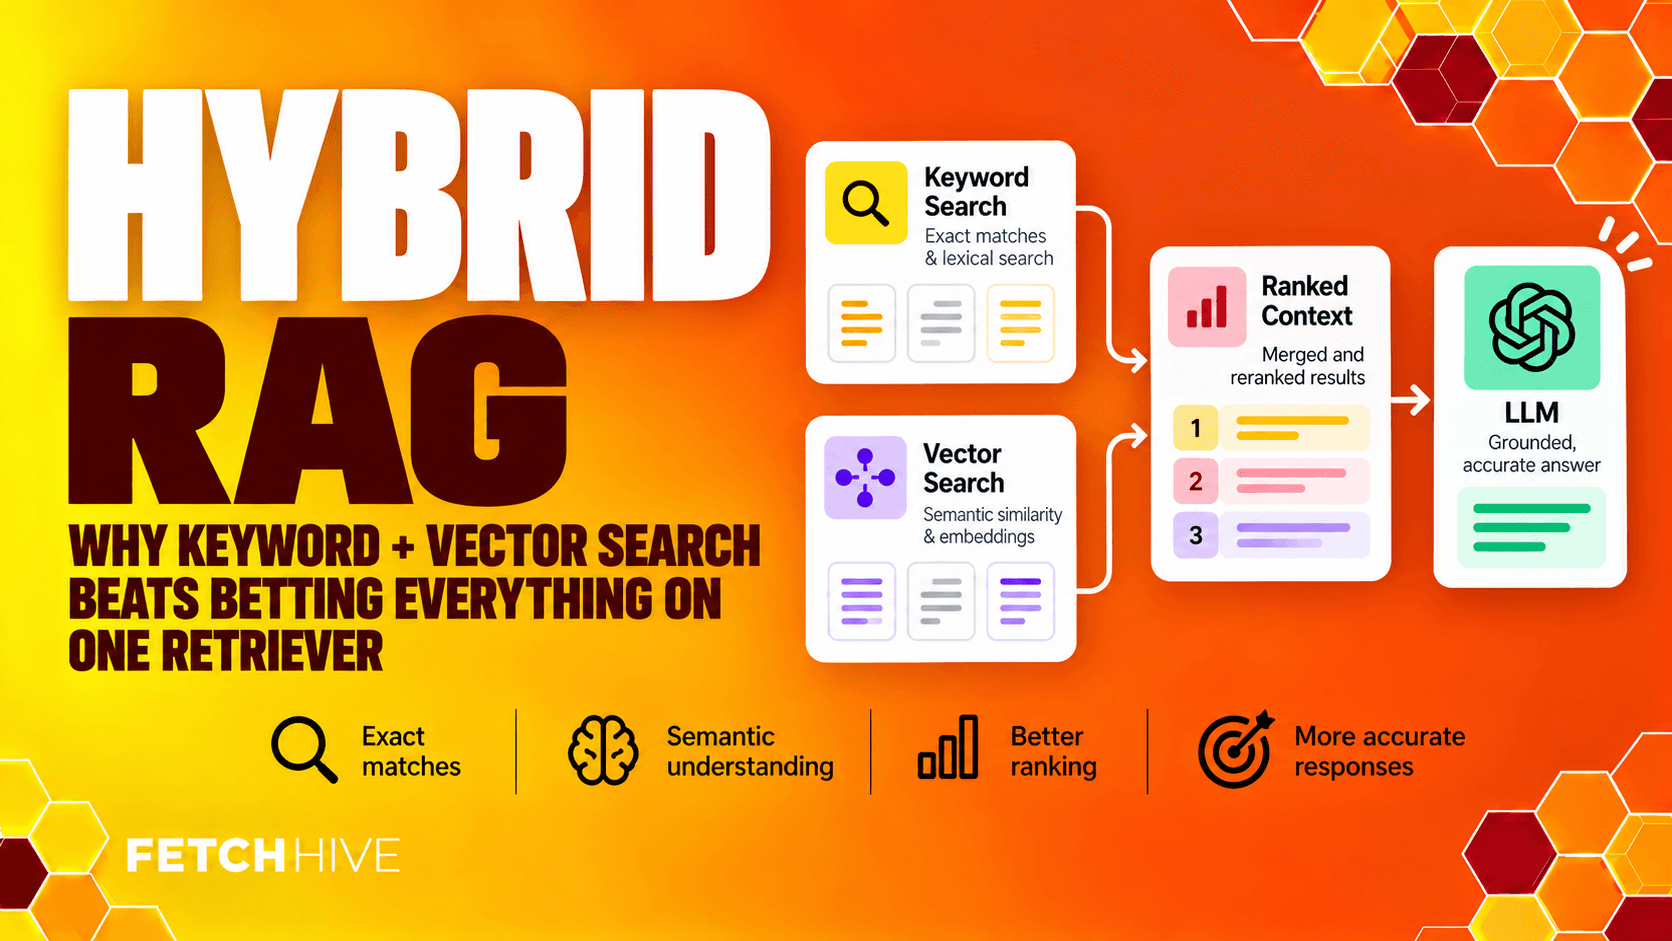
RAG evaluation is how you stop testing by vibes. Instead of asking whether the answer looks good, you measure whether the retrieval process found the right evidence, whether the generated response stayed grounded in that evidence, and whether the final response actually solved the user's problem. The useful RAG evaluation metrics are the ones that tell you which part failed, not just whether the final answer looked convincing.
If you are new to retrieval augmented generation, start with RAG explained. If your system is already built and the answers are a bit rubbish, the RAG performance guide is probably the better starting point. This guide is about the measurement layer: evaluation datasets, evaluation metrics, retrieval quality, generation quality, human evaluation, LLM as a judge, and the feedback loop that tells you what to fix next.
The short version: what should you measure?
A useful RAG evaluation framework measures more than one thing because a RAG system can fail in more than one place. The retriever can miss the relevant documents. The reranker can put the wrong chunk first. The language model can ignore perfectly good retrieved context. Or everything can technically work while the answer is still slow, expensive or useless to the person asking.
Retrieval quality: Did the retrieval component find the relevant information, and did it rank that information high enough to be useful? Think context recall, context precision, MRR and document relevance.
Generation quality: Did the model output produce a correct answer, stay faithful to the retrieved context, and answer the user query directly? Think answer correctness, answer relevance and factual accuracy.
End-to-end usefulness: Did the user actually get what they needed? Task success, resolution rate, feedback and repeated follow-up questions matter here.
Operational performance: What did the request cost, how long did retrieval and reranking take, and did latency get worse when you improved accuracy?
Safety and governance: Did the system expose sensitive data, cite the wrong source, ignore permissions, or confidently surface information the user should never have seen?
You do not need forty RAG metrics on day one. Pick a small set that maps to the failure modes you actually care about. A dashboard containing seventeen beautiful scores nobody uses is still just expensive wallpaper.
What is RAG evaluation actually evaluating?
A production RAG pipeline has several moving parts. I have broken the full RAG architecture and the RAG pipeline from ingestion to generation down separately, but for evaluation the important thing is that you can inspect each stage instead of treating the whole system as one mysterious AI box. Retrieval augmented generation systems are multi-component systems, which is exactly why a single end score is rarely enough.
1. Ingestion and source documents. Your external data, internal knowledge bases, PDFs, APIs and other external knowledge sources have to be current, readable and permissioned correctly.
2. Chunking. Chunking strategies decide what a retrievable unit actually is. Bad chunks can destroy retrieval accuracy before the embedding model gets a chance to help.
3. Embedding and indexing. An embedding model turns text into vectors and stores them in a vector database or another retrieval index.
4. Retrieval. The retrieval component uses the user query to find relevant documents. Dense search, sparse retrieval, filters and hybrid methods can all sit here.
5. Reranking and context assembly. The system decides which retrieved documents deserve to become relevant context for the model.
6. Generation. A large language model reads the prompt and produces the final response.
7. Monitoring and evaluation. You log retrieved context, model output, latency, cost, evaluation scores and user feedback so you can tell which component failed.
That last point is the one people skip. If you only save the final response, you can tell that something went wrong but not why. Evaluating RAG systems properly means keeping enough trace data to separate a bad retrieval from a bad generation.

Build an evaluation dataset that looks like reality
Your evaluation dataset is the foundation. If the test data contains twenty beautifully written FAQ questions that your engineering team already knows the system can answer, congratulations, you have built an evaluation process that measures your ability to write easy tests.
Good evaluation datasets should reflect real user intent. Pull questions from support tickets, search logs, customer conversations, internal Slack or Teams threads, failed queries and thumbs-down feedback. Include normal questions, ugly questions, typos, acronyms, exact product IDs, ambiguous wording and the awkward edge cases that caused somebody to open a bug report at 4:47 on a Friday.
For each query, store as much ground truth as you can reasonably maintain:
The expected or correct answer, when a single correct answer makes sense.
The source documents or document chunks that contain the answer.
Any reference answers that are known to be acceptable.
Important constraints, such as region, permissions, date, product version or customer tier.
The evaluation criteria that define a pass. For example: must cite the current policy, must not mention the archived policy, and must refuse if the evidence is missing.
Ground truth matters most for retrieval quality evaluation because you need to know what the system should have found before you can calculate context recall or retrieval accuracy. It also gives you a stable way to compare changes to the RAG component over time.
Real queries first, synthetic data second
Synthetic data generation is useful when your real dataset is still small. You can sample chunks from the knowledge base and ask a language model to generate realistic questions, answers and source labels. That gives you broader coverage quickly and is particularly useful for domain specific datasets where some topics rarely appear in production logs.
But synthetic data is a supplement, not a substitute. A model generating questions from a document tends to create questions that are suspiciously well matched to that document. Real people are less considerate. They omit nouns, use internal jargon, misspell names and ask things like 'does this still apply to the old enterprise plan?' with absolutely no other context.
A sensible test dataset mixes both. Use real queries for realism, synthetic data for coverage, and keep refreshing the dataset as the knowledge base changes. Treat evaluation datasets as living product assets rather than a spreadsheet you create once and forget.

Evaluate retrieval quality first
When a RAG system gives a bad answer, I would inspect retrieval before blaming the model. The best language model in the world cannot produce a reliable answer from evidence it never received. If the relevant document is sitting at rank 47, prompt engineering is not your first problem. Document retrieval is the first thing to verify because everything downstream depends on it.
The most useful retrieval metrics are boring, which is excellent because boring things are easier to reason about:
Metric | What it tells you | Question it answers |
Context recall / Recall@k | Whether the required evidence appeared in the retrieved set. | Did we fetch everything needed to answer? |
Context precision / Precision@k | How much of the retrieved context was actually useful. | Are we feeding the model signal or a pile of vaguely related text? |
MRR | How high the first relevant result appears. | Did the useful evidence win early enough? |
Hit rate | Whether at least one relevant result appeared in the top-k. | Does retrieval succeed at all for this query? |
Document relevance | How relevant each retrieved document is to the query. | Are the retrieved documents genuinely related to the user's intent? |
Context recall is especially useful when an answer needs several pieces of evidence. If a query requires a pricing rule, a region restriction and a product version, finding one of those three is not enough. Context precision catches the opposite problem: retrieving twelve chunks when only two are relevant. More context is not automatically better. Sometimes it is just more rubbish for the model to read.
MRR is handy when the first relevant result matters. If the correct document always appears somewhere in the top 20 but the first five slots are noise, your retrieval system technically has recall and practically has a problem.

Then evaluate generation quality
Once retrieval is good, look at generation quality. This is where the generated response can still go wrong even when the right evidence is sitting in the prompt.
Answer correctness: Does the generated response match the ground truth or otherwise produce a correct answer?
Answer relevance: Does the response actually address the user query, or did the model answer a nearby question nobody asked?
Faithfulness / grounding: Are the claims supported by the retrieved context? A fluent answer that invents one extra detail is still a bad answer.
Factual accuracy: Are the factual claims correct when checked against authoritative source documents?
Completeness: Did the final response cover all necessary parts of the request?
Instruction following: Did the language model respect citation requirements, formatting rules, refusal rules and other evaluation criteria?
Answer relevance and correctness are not the same thing. A response can be perfectly grounded in the wrong document. It can also be factually correct but fail to answer the question. That is why one giant 'quality score' tends to hide more than it reveals.

Ground truth vs reference-free evaluation
There are two useful ways to evaluate a generated response, and mature RAG evaluation methods normally use both.
Reference-based evaluation
Reference-based evaluation compares the model output against a known correct answer or reference answers. This works well when your domain has stable answers: support policies, product documentation, technical procedures, compliance rules or other cases where you can define ground truth.
Semantic similarity can be a cheap first pass. Embed the generated response and the reference answer, then compare the vectors. It is useful for spotting obviously unrelated answers, but it is not a substitute for correctness. Two answers can be semantically similar while disagreeing on the one number that actually matters. Traditional statistical metrics can still be useful as secondary signals for rigid outputs, but they are usually too blunt to judge open-ended RAG answers on their own.
Reference-free evaluation
Reference free evaluation is what you use when no single answer exists or maintaining labels for every query would be ridiculous. The judge sees the question, retrieved context and generated response, then scores things like faithfulness, context relevance, answer relevance and completeness.
This is extremely useful for production monitoring because content changes faster than humans can relabel everything. It also lets you evaluate new external data or newly indexed source documents without rebuilding the entire ground truth set first.
LLM as a judge is useful. It is not an oracle.
LLM as a judge has made large-scale RAG evaluation much easier. You can run thousands of responses through an evaluation prompt and get structured evaluation scores for answer correctness, context relevance, faithfulness, style and other criteria.
The danger is obvious: now an AI model is grading another AI model, and everyone quietly hopes the numbers are science.
Use judge models, but calibrate them. Keep a sample of human evaluation alongside the automated evaluation process. If humans consistently disagree with the judge on a particular class of query, fix the rubric, the evaluation prompt or the judge model before treating its score as truth.
Define each metric clearly. 'Good answer' is not an evaluation criterion.
Give the judge the minimum evidence it needs, especially the user query, retrieved context and any ground truth.
Use pass/fail or small scales where possible. A 0–100 score often creates fake precision.
Run repeated judgments on borderline examples to see how stable the judge is.
Periodically compare judge decisions with human evaluation from domain experts.
Human evaluation is slower and more expensive, but it remains the sanity check for subtle requirements, high-risk answers and judge calibration. You do not need humans to grade every request. You need enough human review to know whether the automated grader is still living on the same planet as your users.

Evaluate the embedding model with your data, not somebody else's leaderboard
The embedding model directly affects retrieval quality, so any serious evaluation framework should test it separately. I covered model selection in the RAG embeddings guide, and the same rule applies here: benchmark on your own queries and documents. Large language models only see the evidence that retrieval gives them, so retrieval quality still sets the ceiling for the final answer.
Hold the rest of the RAG pipeline constant. Re-index the same evaluation dataset with each candidate embedding model, run the same user queries, then compare context recall, context precision, MRR, latency and downstream answer correctness. Otherwise you change three things at once and learn absolutely nothing.
The same goes for storage and search configuration. Your vector database can affect filtering, hybrid retrieval, latency and operational behaviour, but a new database is not a magic retrieval-quality button. Test the retrieval component before and after the change.
Also test query variation. Replace exact words with paraphrases, introduce typos, use abbreviations and ask the same thing in several different ways. A system that only works when the user phrases the question like your test author is not robust. It has memorized the exam.

Evaluate chunking, reranking and retrieval strategy as separate experiments
Chunking strategies, sparse retrieval, hybrid search, metadata filters and reranking all affect what becomes relevant context. Treat each one like an experiment.
1. Freeze the evaluation dataset.
2. Choose one variable to change.
3. Run the same retrieval quality evaluation before and after.
4. Compare the key metrics and inspect the failures, not just the averages.
5. Keep the change only if it fixes the problem you were trying to solve without creating a worse one somewhere else.
This is where the RAG performance guide and adaptive vs corrective RAG become useful companions. Retrieval can be improved with better search, reranking and correction loops, but evaluation is what tells you whether those additions actually helped.
End-to-end metrics: did the user actually get a useful answer?
Component metrics are diagnostic. End-to-end metrics tell you whether the product worked. At this layer, the question is simple: are users getting correct responses reliably enough for the product to do its job?
Task success: Did the user accomplish what they came to do?
Resolution rate: Did the conversation resolve without escalation or another support channel?
User feedback: Thumbs up/down, CSAT, explicit corrections and abandonment all tell you something the offline test dataset cannot.
Consistency: Does the system give compatible answers when the same question is asked more than once?
Cost per correct response: A cheaper model is not actually cheaper if it doubles the number of failed answers.
A drop in system performance at this layer does not tell you the cause. It tells you where to start digging. If task success falls, look at the component metrics and traces underneath it. Maybe retrieval accuracy dropped after an index update. Maybe generation quality changed after a model swap. Maybe latency is so bad that users give up before the correct answer arrives.
Do not forget multi-turn and agentic RAG
Single-turn evaluation is not enough for chat systems. A RAG application can answer turn one perfectly and still fall apart by turn six because the conversation history becomes noisy, the retrieval query drifts or the model starts treating an old answer as new evidence.
For multi-turn evaluation, test whole sessions. Measure whether the system preserves constraints, avoids contradicting itself, retrieves new evidence when the topic changes and stops re-fetching the same irrelevant chunks.
The problem gets more obvious in agentic RAG systems. An agent may retrieve, inspect, call another tool, search again and verify before producing the final answer. Evaluating RAG systems like this means checking intermediate decisions as well as the response the user eventually sees.
Did the agent choose the right retrieval method?
Did it use the correct external knowledge source?
Did it search again when the first retrieval was weak?
Did it stop when it had enough evidence?
Did a bad intermediate step contaminate everything downstream?
The more complex systems become, the less useful a single final evaluation score becomes. You need traces.

A practical RAG evaluation workflow
You do not need to turn this into a research project. A useful evaluation process can be surprisingly simple.
1. Create the evaluation data. Start with real user queries, expected sources and ground truth where it exists. Add synthetic data where you need broader coverage.
2. Run retrieval evaluation. Capture retrieved documents and calculate context recall, context precision, MRR or whatever RAG metrics match your use case.
3. Run generation evaluation. Score answer correctness, answer relevance, grounding and any domain-specific rules.
4. Review failures. Sort the worst cases into clusters. Missing document? Wrong chunk? Bad rerank? Prompt problem? Language model problem? Stale knowledge base?
5. Change one thing. Do not swap the embedding model, chunk size, reranker and prompt in the same experiment unless your goal is to learn nothing.
6. Re-run the same test dataset. Compare evaluation scores and inspect the changed failures.
7. Promote useful failures into regression tests. Every new bug becomes valuable data for the next run.
Over time, the failure library becomes more useful than the original benchmark. It contains the weird, domain-specific ways your own users break your own system. No generic benchmark can give you that.
Continuous evaluation: put the tests in the deployment loop
RAG development does not stop when you ship. Documents change. External data changes. Models change. Prompts change. Indexes get rebuilt. A configuration that worked last month can quietly degrade even if nobody touched the application code. Changes to models, source content and training data assumptions can all move system behaviour over time.
Continuous evaluation means running a useful subset of the evaluation framework whenever important parts of the system change, then sampling live traffic for production monitoring.
Run systematic testing before major RAG pipeline changes are deployed.
Compare evaluation metrics against the previous baseline rather than looking at the new score in isolation.
Block or flag regressions on critical queries.
Sample live requests for reference free evaluation and hallucination checks.
Track production monitoring signals alongside model version, index version, prompt version and retrieval configuration.
Refresh evaluation datasets when the knowledge base or source documents change.
This is one of the places where good observability stops being optional. If an evaluation score drops, you want to open the trace and see the query, retrieved documents, reranking, prompt, model output, latency and cost. Otherwise continuous evaluation just gives you a red number and a fresh mystery.
That obsession with seeing the boring bits is also why Fetch Hive traces workflow and agent execution. The product mention is deliberately small here because the principle matters more than the tool: if you cannot inspect the retrieval and generation path, debugging RAG gets stupidly expensive.

Safety, permissions and sensitive data belong in the evaluation set
Accuracy is not the only way a RAG application can fail. A system can produce a factually perfect answer from a document the user was never allowed to access.
Add adversarial and permission-sensitive cases to the test dataset. Include source documents containing sensitive data, conflicting permissions, prompt injection attempts inside retrieved text, outdated policies and questions that should be refused.
Can the user retrieve information outside their permission scope?
Can instructions hidden in retrieved context override the system rules?
Does the answer cite the correct current source instead of an archived copy?
Does the model disclose sensitive data when the correct behaviour is to refuse?
Does the system remain grounded when external knowledge sources disagree?
These are not nice-to-have checks for regulated or internal knowledge bases. They are part of answer correctness.
Map metrics to failure modes, not dashboards
A metric is useful when it helps you decide what to inspect next. This is the failure map I would keep next to the evaluation dashboard:
What you see | Metric that exposes it | Where to look first |
Correct source never appears | Low context recall / retrieval accuracy | Embedding model, chunking, filters, indexing |
Too much irrelevant context | Low context precision | Top-k, reranker, hybrid or sparse retrieval settings |
Good retrieval, wrong answer | Low answer correctness with strong retrieval metrics | Prompt, language model, context handling |
Answer sounds good but invents details | Low faithfulness / factual accuracy | Grounding prompt, model, conflicting context |
Works for exact wording only | Large score variance across paraphrases | Embedding robustness, query rewriting, retrieval strategy |
Gets worse after document updates | Regression in evaluation scores after re-index | Knowledge base freshness, source documents, index version |
Slow but accurate | High latency with stable quality | Reranking, top-k, model size, retrieval calls |
This is much more useful than staring at one average evaluation score and arguing about whether 0.83 is 'good'.

Common RAG evaluation mistakes
Only evaluating the final response. You lose the ability to tell retrieval failure from generation failure.
Only using synthetic questions. The system performs beautifully on questions created from the same documents it is retrieving. What a shock.
Copying somebody else's thresholds. Different RAG applications have different risk, query complexity and acceptable trade-offs.
Changing several components at once. You get a new score and no idea which change caused it.
Ignoring low-frequency failures. A rare compliance error can matter more than a hundred perfect FAQ answers.
Treating the judge score as truth. LLM evaluation methods need calibration and human evaluation.
Never refreshing the dataset. Your knowledge base evolves while your benchmark stays frozen in time.
Stopping after launch. Production monitoring is part of RAG evaluation, not a separate hobby for later.
A sensible starter metric set
If you want a compact set of key metrics without turning the project into a spreadsheet competition, I would start here:
Context recall: are we retrieving the evidence needed to answer?
Context precision: how much of the retrieved context is useful?
MRR: how early does the first relevant result appear?
Answer correctness: is the final answer actually right?
Answer relevance: did we answer the question the user asked?
Faithfulness: are the claims supported by retrieved context?
Task success or resolution rate: did the user get the outcome they needed?
Latency and cost per correct response: can we deliver that quality at a sensible operational cost?
That gives you retrieval metrics, generation metrics, user value and system performance without collecting numbers for the sake of collecting numbers. Add domain-specific evaluation criteria when the application genuinely needs them.

RAG evaluation should make debugging boring
That is the goal. Not a perfect benchmark. Not a leaderboard. Not a dashboard with enough decimals to frighten an accountant.
You want a repeatable evaluation process that tells you what broke, which RAG component caused it, whether the fix actually improved things, and whether the same failure comes back six weeks later.
Start with real user queries. Build a ground truth set where you can. Measure retrieval and generation separately. Use reference free evaluation where labels are impractical. Use LLM as a judge for scale, human evaluation for calibration, and continuous evaluation so the system does not quietly decay in production.
Most importantly, keep turning failures into tests. The more your evaluation dataset reflects the ugly questions real users actually ask, the less likely you are to discover those failures for the first time in production.
A simple way to start this week
Take 50 to 100 real user queries and label the expected source or answer where you can.
Run retrieval and generation evaluation separately so one good final answer cannot hide bad retrieval.
Pick a small set of RAG metrics you will actually use, then record a baseline before changing anything.
Turn every useful failure into a regression test and keep the evaluation dataset alive as the knowledge base changes.
Share this post